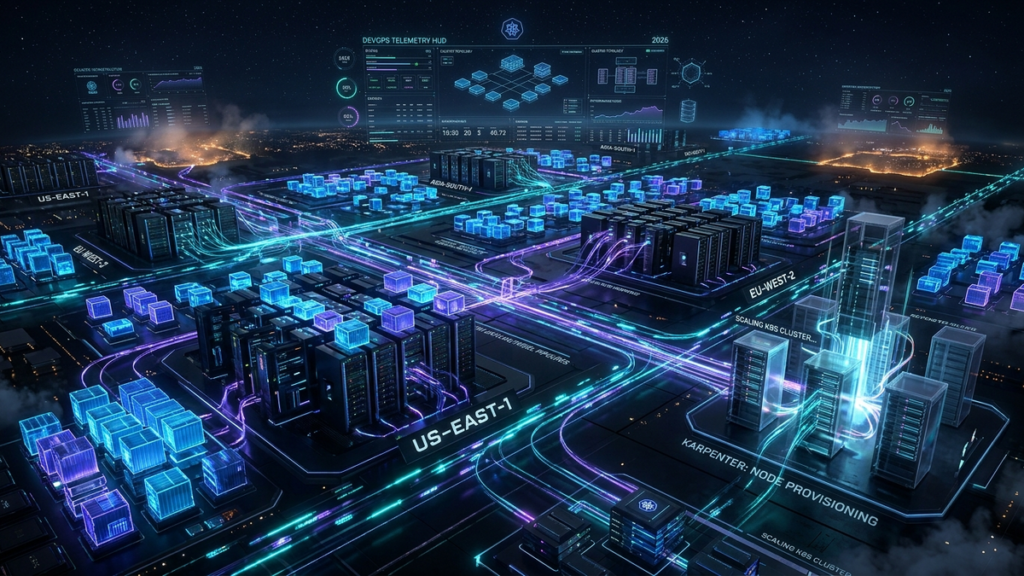
Kubernetes has definitively won the container orchestration wars, becoming the de facto operating system of cloud-native computing. However, while managing a 3-node development cluster on a cloud managed service is straightforward, operating Kubernetes at enterprise scale—hundreds of clusters, tens of thousands of dynamic pods, multi-terabyte stateful databases, and multi-million-dollar monthly cloud infrastructure bills—introduces severe operational friction.
In 2026, legacy tools like the Kubernetes Cluster Autoscaler (CAS) and iptables-based kube-proxy have reached their architectural limits. Modern platform engineering teams are standardizing on next-generation cloud-native primitives: Karpenter for just-in-time node provisioning and Cilium eBPF for sub-millisecond networking. At Ghayma LLC, our DevOps and Site Reliability Engineering (SRE) practice designs hyperscale Kubernetes foundations that maximize availability while drastically cutting cloud spend.
1. The Autoscaling Revolution: Why Karpenter Replaces Cluster Autoscaler
The traditional Kubernetes Cluster Autoscaler operates under rigid constraints: it manages infrastructure through static cloud Auto Scaling Groups (ASGs). When a pod requires compute, the autoscaler must launch a homogeneous EC2/GCE instance matching the group’s predefined type. Launching nodes typically requires 3 to 8 minutes, and instances often run at 30% utilization due to awkward CPU/memory packing ratios.
Karpenter: Dynamic, Group-Less Just-in-Time Provisioning
Originally developed by AWS and now open-source CNCF, Karpenter operates directly with cloud provider hypervisors, bypassing Auto Scaling Groups entirely:
- Sub-45 Second Provisioning: Karpenter observes unschedulable pods and launches tailor-made compute instances in under a minute.
- Right-Sizing Machine Bin-Packing: If pending pods demand 14 CPU cores and 52 GB RAM, Karpenter provisions an exact single instance matching those parameters rather than spinning up two wasteful 16-core behemoths.
- Automated Cost Consolidation: Karpenter continuously audits running nodes. If three under-utilized nodes can be safely drained and condensed onto a single smaller spot instance, it automatically consolidates them, slashing AWS/GCP bills by 35% to 50%.
2. Eliminating Network Bottlenecks: Replacing Kube-Proxy with eBPF
In legacy Kubernetes, every cluster service relies on kube-proxy, which writes routing rules into the Linux kernel’s iptables. While iptables works adequately for 500 services, routing rules grow quadratically:
| Service Scale | kube-proxy (iptables) Packet Latency | Cilium (eBPF) Packet Latency | Throughput Differential |
|---|---|---|---|
| 100 Services | 0.2 ms | 0.08 ms | Negligible |
| 2,500 Services | 4.5 ms | 0.12 ms | Cilium is 37x faster |
| 10,000 Services | 18.0 ms (Linear O(N) packet scan) | 0.15 ms (O(1) BPF Map hash lookup) | Cilium is 120x faster |
By bypassing the entire Linux network stack and routing packets directly between sockets at the kernel level via BPF map hashes, Cilium eradicates network jitter and eliminates packet loss during high-traffic flash sales or DDoS spikes.
3. Multi-Cluster Fleet Management and GitOps Architecture
In 2026, enterprise resilience requires that no single disaster—whether an AWS regional outage or a catastrophic cluster upgrade failure—can take down corporate services. Organizations mandate a Fleet Topology distributed across multiple geographic regions and cloud providers.
The GitOps Declarative Delivery Pipeline
Fleet management is coordinated via ArgoCD or Flux: Git repositories serve as the absolute single source of truth for all cluster declarations:
apiVersion: argoproj.io/v1alpha1
kind: ApplicationSet
metadata:
  name: "global-microservices-fleet"
spec:
  generators:
  - clusters: {} # Automatically syncs across all registered global clusters
  template:
    spec:
      source:
        repoURL: "https://github.com/ghayma-enterprise/fleet-manifests"
        targetRevision: "HEAD"
        path: "apps/production"
      destination:
        server: "{{server}}"
        namespace: "prod-services"
When an engineer merges a pull request to the main branch, ArgoCD orchestrates progressive canary deployments across US-East, Europe-Central, and Asia-Pacific clusters simultaneously, monitoring Prometheus telemetry and automatically rolling back if error rates spike above 0.1%.
4. FinOps: Cost Governance and Resource Allocation
Cloud spend without visibility leads to runaway bills. Modern platform teams deploy Kubecost or OpenCost to allocate infrastructure expenses directly to individual product squads, engineering domains, and business units. SREs enforce strict ResourceQuotas and LimitRanges, preventing runaway memory leaks from consuming cluster capacity.
“Operating Kubernetes at scale is not about memorizing kubectl commands; it is about building self-healing platform abstractions that empower hundreds of developers to deploy software continuously without ever worrying about the underlying servers.”
Conclusion
Scaling Kubernetes to tens of thousands of workloads requires modern cloud-native primitives. By replacing legacy node autoscalers with Karpenter, turbocharging the network plane with Cilium eBPF, and standardizing global deployments on declarative GitOps fleets, enterprise technology organizations achieve unbeatable reliability, sub-second latency, and ruthless cloud cost efficiency.