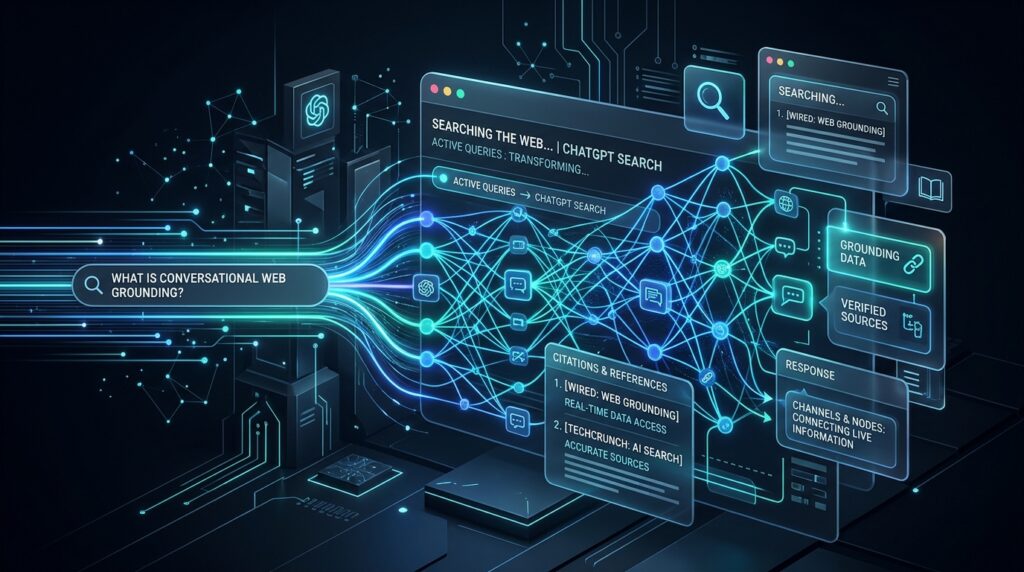
In early November 2024, OpenAI formally transitioned ChatGPT from a static predictive knowledge repository into an active, real-time web exploration engine. Evolving directly out of its exploratory SearchGPT prototype, the native integration of ChatGPT Search into the production ChatGPT interface marks one of the most consequential shifts in information retrieval since Google introduced PageRank in 1998. Rather than forcing users to sift through sponsored links, algorithmically inflated SEO landing pages, and fragmented snippets across traditional search results, conversational search synthesizes verified real-time web knowledge with deep contextual reasoning.
For software architects, enterprise data engineers, and web system designers, understanding the technical mechanics powering ChatGPT Search is vital. This comprehensive whitepaper explores the underlying engineering pipeline: autonomous query intent routing, fine-tuned model distillation on GPT-4o, the construction of real-time citation graphs, publisher ecosystem dynamics, and practical strategies for integrating grounded search into modern enterprise applications.
1. The Great Decoupling: Beyond the Ten Blue Links
Traditional search engines operate on a fundamentally decoupled three-stage pipeline: asynchronous web crawling, inverted index construction, and heuristic ranking based on query-document lexical similarity and link topology. While this paradigm scaled the modern internet, it introduced severe frictions for complex knowledge work:
- The Synthesizing Burden: Users are forced to open multiple browser tabs, evaluate disparate sources, reconcile conflicting data, and manually synthesize an answer.
- Query Fragility: Multi-hop inquiries—such as “Compare the memory allocation overhead of Go 1.23 arenas versus Rust jemalloc under high TCP concurrency and cite benchmark papers from this month”—cannot be resolved by standard lexical spiders without manually decomposing the request into five separate searches.
- Commercial Misalignment: Search engines monetization models rely on maximizing ad impressions and intermediate click-throughs, structurally disincentivizing immediate, direct answer delivery.
ChatGPT Search resolves this friction by integrating a real-time retrieval-augmented generation (RAG) pipeline directly into the autoregressive decoding loop of GPT-4o. The user interacts not with an index query parser, but with a persistent conversational reasoning agent capable of maintaining context across multi-turn investigations.
2. The Search Execution Pipeline: Autonomous Intent Routing
Running a full web retrieval cycle for every conversational prompt would introduce unacceptable latency and compute cost. A query such as “Explain the time complexity of QuickSort” requires zero web grounding, whereas “What were the key takeaways from yesterday’s Federal Reserve policy press conference?” is entirely unanswerable from pre-training weights alone.
To balance speed, cost, and factual recency, OpenAI deployed an autonomous Query Intent Classifier operating as a lightweight prefix stage ahead of primary generation. The routing pipeline follows a strict mathematical decision tree:
- Temporal Horizon Analysis: The incoming prompt is evaluated for temporal indicators (e.g., explicit dates, words like “current”, “latest”, “breaking”, “today”, “yesterday”, or stock tickers).
- Static Knowledge Entropy Check: The classifier computes the uncertainty score of the base model’s parametric memory regarding the entity in question. High entropy triggers a retrieval signal.
- Manual User Override: Users retain deterministic control via a dedicated search toggle, bypassing the classifier when fresh verification is explicitly demanded.
When the classifier identifies retrieval necessity, it initiates an asynchronous sub-graph execution. The user’s natural language query is translated into multiple optimized search strings tailored for both traditional lexical spiders and dense vector indices.
3. Model Distillation and Latency Engineering on GPT-4o
The primary technical barrier to real-time conversational search has historically been latency. Standard frontier models processing multi-megabyte web scrape payloads can require between 5 to 12 seconds to generate a coherent response—an eternity for consumer search expectations where sub-second response times are the standard.
To overcome this bottleneck, OpenAI trained a highly specialized, distilled variant of GPT-4o specifically optimized for search summarization. Model distillation transfers the knowledge and reasoning capabilities of an uncompressed teacher model into a compact, low-latency student architecture:
High-Level Distillation Objective:
L_total = alpha * L_CE(P_student, Y_ground_truth) + (1 - alpha) * L_KL(P_student, P_teacher)

Where:
- L_CE represents cross-entropy loss against curated citation datasets.
- L_KL represents Kullback-Leibler divergence matching the teacher's probability distribution.
- alpha balances factual ground truth accuracy against reasoning fidelity.
This specialized model exhibits exceptional performance across three core latency-critical tasks:
- Document Pruning & Extraction: Rapidly parsing raw HTML payloads, stripping boilerplate (navigation bars, ads, tracking scripts), and isolating high-signal content blocks.
- Contradiction Reconciliation: Identifying discrepancies across multiple real-time news sources and flagging divergent reporting to the user.
- Streaming Synthesized Generation: Beginning token generation within 400 milliseconds of web fetch completion, utilizing server-sent events (SSE) to deliver perceived instantaneous results.
4. The Citation Graph: Mitigating Hallucinations via Strict Grounded Decoding
The central vulnerability of generative language models is hallucination—the confident assertion of fabricated facts arising from statistical token probabilities. In a search engine, hallucination is fatal to user trust.
ChatGPT Search attacks this challenge through a deterministic Citation Graph. Every factual claim emitted by the model during generation is bound to an exact URI and verified text fragment extracted during the search phase. If a proposed token sequence cannot be traced back to an explicit token span in the retrieved document corpus, the model’s internal safety filters suppress the generation and re-prompt the retrieval subsystem.
The resulting user interface renders interactive inline citations. Hovering over a reference surfaces the source title, domain authority metadata, and the exact excerpt supporting the statement, allowing technical users to immediately inspect primary documentation.
5. Publisher Economics and The Technical Standardization of AI Web Crawling
The shift to generative search has precipitated intense legal and economic debates between frontier AI laboratories and digital publishers. When an AI agent provides complete answers directly within the interface, downstream referral traffic to content creators risks catastrophic decline.
OpenAI pursued a two-pronged strategy to address publisher relationships: exclusive content licensing agreements with premier international media organizations (including Axel Springer, Associated Press, Financial Times, Condé Nast, and Le Monde), paired with technical governance standards.
Critically, this week witnessed major industry consensus: OpenAI, Google, Microsoft, and Anthropic aligned on standardizing crawler directives within robots.txt. Through protocols like __usage_ai-training and differentiated user-agent strings (e.g., OAI-SearchBot vs GPTBot), publishers can now allow real-time search indexing—preserving visibility in conversational queries—while strictly barring their intellectual property from being ingested into foundation model pre-training corpora.
6. Practical Architecture: Building Grounded Search Agents via API
Enterprise engineering teams can leverage similar real-time grounding architectures within their internal stacks. Below is a production-grade TypeScript implementation utilizing modern function calling and real-time retrieval to generate grounded, verified technical answers:
import { OpenAI } from 'openai';

interface SearchResult {
  title: string;
  url: string;
  snippet: string;
}

const openai = new OpenAI({ apiKey: process.env.OPENAI_API_KEY });

async function executeRealtimeSearch(query: string): Promise<SearchResult[]> {
  // In production, connect to a compliant search provider (e.g., Bing, Brave, or internal elastic cluster)
  const response = await fetch(`https://api.searchprovider.io/v1/search?q=${encodeURIComponent(query)}&count=5`, {
    headers: { 'Authorization': `Bearer ${process.env.SEARCH_API_KEY}` }
  });
  const data = await response.json();
  return data.results.map((r: any) => ({
    title: r.title,
    url: r.url,
    snippet: r.description
  }));
}

export async function generateGroundedResponse(userPrompt: string): Promise<string> {
  // 1. Determine search requirements and extract optimal queries
  const routingPrompt = [
    { role: 'system', content: 'You are an autonomous search coordinator. If the user prompt requires fresh or factual external data, emit a JSON array of search strings. If not, emit an empty array.' },
    { role: 'user', content: userPrompt }
  ];

  const routingResponse = await openai.chat.completions.create({
    model: 'gpt-4o-mini',
    messages: routingPrompt as any,
    response_format: { type: 'json_object' }
  });

  const { queries } = JSON.parse(routingResponse.choices[0].message.content || '{"queries":[]}');

  let searchContext = '';
  if (queries && queries.length > 0) {
    const searchPromises = queries.map((q: string) => executeRealtimeSearch(q));
    const rawResults = (await Promise.all(searchPromises)).flat();

    searchContext = rawResults.map((item, idx) =>
      `[Source ${idx + 1}]: ${item.title}nURL: ${item.url}nContent: ${item.snippet}n`
    ).join('n---n');
  }

  // 2. Synthesize final grounded answer with strict citation constraints
  const finalMessages = [
    {
      role: 'system',
      content: `You are an expert enterprise research engineer. Answer the user prompt using ONLY the provided verified context.
Every factual assertion must include a citation in the format [Source X](URL). If the context is insufficient, state so explicitly.

VERIFIED CONTEXT:
${searchContext || 'No external web context required.'}`
    },
    { role: 'user', content: userPrompt }
  ];

  const completion = await openai.chat.completions.create({
    model: 'gpt-4o',
    messages: finalMessages as any,
    temperature: 0.2
  });

  return completion.choices[0].message.content || '';
}
7. The Strategic Outlook: Generative Engine Optimization (GEO)
As conversational search capturing expanding market share, the digital marketing and web engineering disciplines must evolve from traditional Search Engine Optimization (SEO) toward Generative Engine Optimization (GEO). The ranking vectors of conversational LLMs differ radically from legacy algorithms:
| Optimization Vector | Legacy Google SEO | Generative Engine Optimization (GEO) |
|---|---|---|
| Primary Metric | Keyword density, backlinks, page load speed | Factual density, semantic authority, citation probability |
| Content Structure | Long-form text optimized for keyword crawling | Structured JSON-LD, clear entity definitions, data tables |
| User Outcome | Drive click-through to external web page | Direct answer synthesis with primary source attribution |
| Index Accessibility | Standard public sitemaps and HTML markup | Direct API feeds, clean DOM trees, robots.txt AI directives |
Organizations that adapt their technical infrastructure to expose structured, verifiable, authoritative data will dominate visibility in the conversational AI era. Explore our related research on Enterprise Security & Data Integrity and test our in-browser developer utilities at the Ghayma Tools Hub.