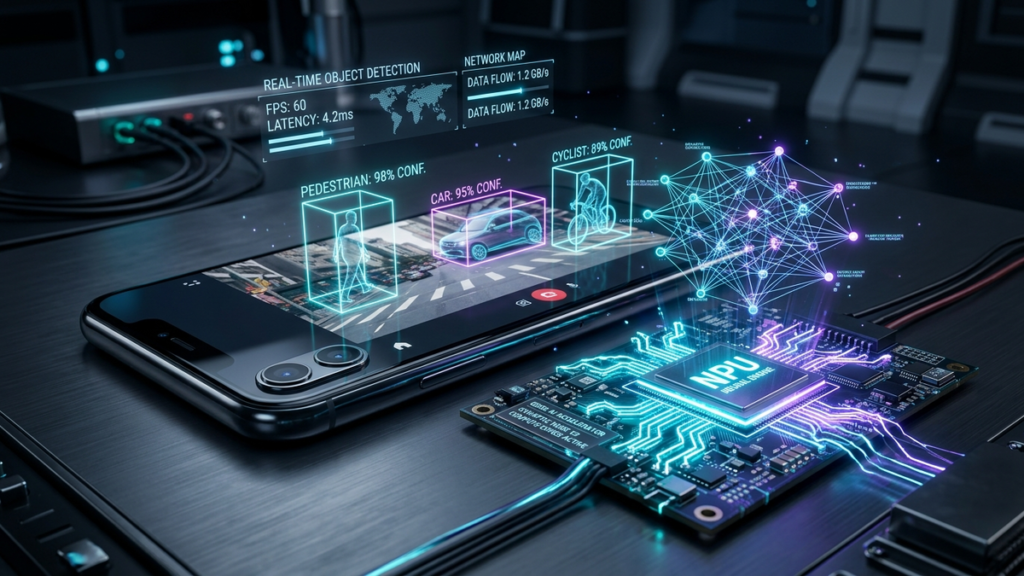
For years, the standard deployment pattern for AI-powered mobile and embedded applications was cloud inference: capturing audio or video on a device, sending a raw stream over cellular data to a remote GPU server, and waiting for an HTTP JSON payload in return. However, in mission-critical applications—including interactive gaming, autonomous robotics, augmented reality, and confidential medical diagnostics—cloud inference fails due to three insurmountable barriers: high latency, massive bandwidth costs, and privacy vulnerabilities.
In 2026, the convergence of specialized Neural Processing Units (NPUs) in consumer silicon (such as Apple’s M-series/A-series Neural Engine and Qualcomm’s Snapdragon X Elite) with unified execution runtimes like ONNX Runtime has made true on-device Edge AI not just feasible, but the preferred engineering standard. At Ghayma LLC, our engineers build native, zero-latency edge pipelines for high-performance applications.
1. The Edge AI Advantage: Latency, Cost, and Privacy
Deploying machine learning models directly on consumer silicon transforms application performance across three vital metrics:
| Dimension | Cloud-Based Inference | On-Device Edge Inference |
|---|---|---|
| End-to-End Latency | 250 ms – 1500 ms (Network dependent) | 4 ms – 25 ms (Deterministic local bus) |
| Cloud Infrastructure Cost | Escalates linearly with user count ($0.01+/call) | $0.00 marginal cost (Client compute) |
| Offline Availability | Zero function without active internet | 100% operational offline |
| Data Privacy & Compliance | Raw user audio/video crosses the wire | Data never leaves device silicon |
2. The ONNX Ecosystem and Execution Providers
Historically, deploying models across divergent hardware required writing disparate codebases in CoreML (iOS), NNAPI (Android), and TensorRT (NVIDIA). The Open Neural Network Exchange (ONNX) solves this fragmentation by establishing an open computational graph standard.
The core superpower of ONNX Runtime (ORT) lies in its modular Execution Provider (EP) architecture. The same trained model weights dynamically compile to the optimal hardware accelerator available on the host machine:
- CoreML Execution Provider: Dispatches operations directly to Apple’s dedicated Neural Engine (ANE) on iPhone and Mac hardware.
- QNN (Qualcomm Neural Network) EP: Leverages the Hexagon NPU on modern Snapdragon mobile and Windows on ARM chipsets.
- DirectML EP: Utilizes DirectX 12 hardware acceleration across any Windows GPU (AMD, Intel, NVIDIA).
- XNNPACK EP: Highly optimized multithreaded CPU floating-point kernels for low-power ARM Cortex cores.
3. Model Optimization: Pruning, Quantization, and Fusion
Foundation models trained in 32-bit floating point (FP32) are far too massive to load into restricted mobile RAM. To achieve 60 frames-per-second real-time inference, engineers execute a disciplined post-training optimization pipeline:
Key Model Compression Techniques
- Operator Fusion: Merging consecutive operations (e.g., combining
Conv2D + BatchNorm + ReLUinto a single atomic hardware kernel), cutting memory bus roundtrips by 65%. - INT8 Quantization: Converting 32-bit weights to 8-bit integers using symmetric calibration datasets. This cuts model memory footprint by 75% with less than 0.5% degradation in accuracy.
- Structured Weight Pruning: Removing redundant zero-valued neural connections to enable streamlined sparse matrix computations.
4. Production Implementation Workflow
A typical end-to-end production pipeline implemented at Ghayma LLC follows these structured milestones:
- Model Training & Export: Train the architecture in PyTorch, then export directly to ONNX format using
torch.onnx.export()with dynamic batch axes. - Optimization with ORT Optimizer: Run graph level optimizations to fuse nodes and prune dead execution branches:
import onnxruntime.tools.optimizer as opt optimized_model = opt.optimize_model("model.onnx", model_type='bert') optimized_model.save_model_to_file("model_opt.onnx") - Calibration & INT8 Quantization: Pass representative domain samples through ONNX Runtime’s static quantizer to determine optimal scaling factors.
- Native Client Binding: Integrate the compiled
.onnxmodel into native Swift (iOS), Kotlin (Android), or C++ (Game Engines) via lightweight ONNX Runtime mobile libraries (< 5MB binary footprint).
“The future of user-facing AI is not in massive monolithic data centers; it is operating quietly, instantaneously, and private by default on the silicon inside your pocket.”
Conclusion
By leveraging ONNX Runtime, hardware-accelerated Execution Providers, and INT8 quantization, developers can deliver fluid, 60fps intelligent user experiences that respect consumer privacy and eliminate recurring server hosting bills. Edge AI inference represents the defining architectural shift for modern mobile, gaming, and enterprise client software.